OTTR AI Studio — self-hosted assistant
A Rust agent runtime with local Ollama and cloud fallback, a NestJS and pgvector dashboard, and a lead-finding pipeline, running on a Mac Mini behind a VPS tunnel.
Background
An always-on assistant for a small agency: it scans job boards for opportunities, scores leads, drafts proposals, reads Gmail and Calendar, and answers questions from a memory wiki. It runs on a Mac Mini that boots straight into the stack and is exposed through a reverse SSH tunnel.
Screens
The problem
The first version ran on OpenClaw. Its system prompts were around twenty thousand characters. On an M1 Mac Mini with 16 GB, small local models stalled for tens of seconds per reply, and sending everything to a cloud model made an always-on assistant too expensive for an agency of our size.
The machine also had to survive power cuts, which are routine in Kathmandu, and come back without anyone touching it.
Approach
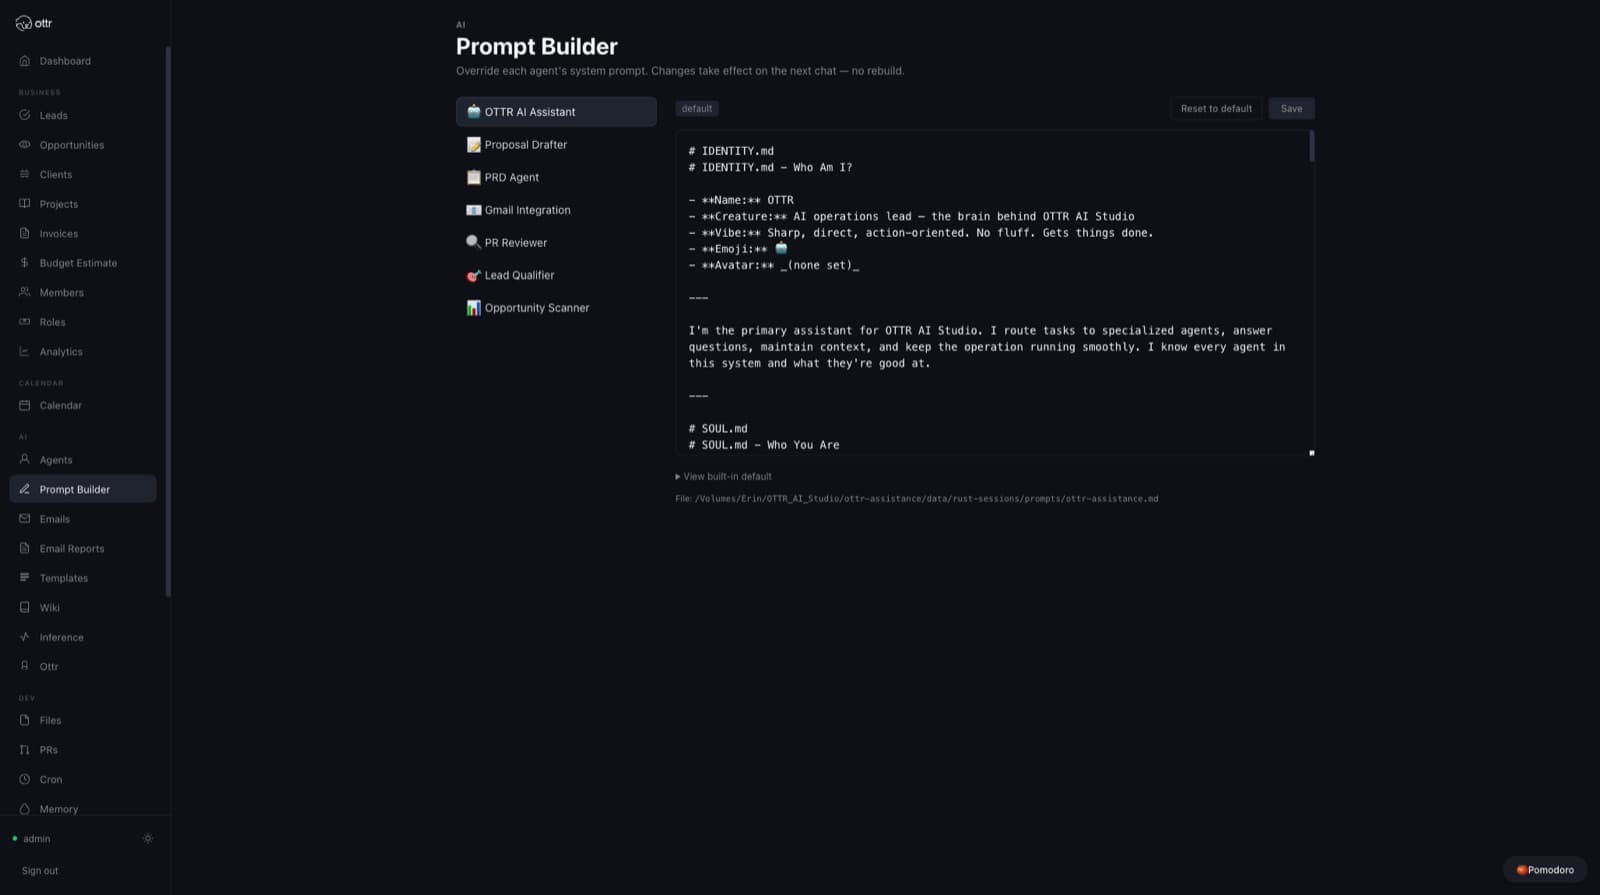
- Replace the runtime with a Rust service on axum. Prompts are kept near five hundred characters, with skills and personas injected only when needed. gemma3:1b answers in under a second on the same hardware.
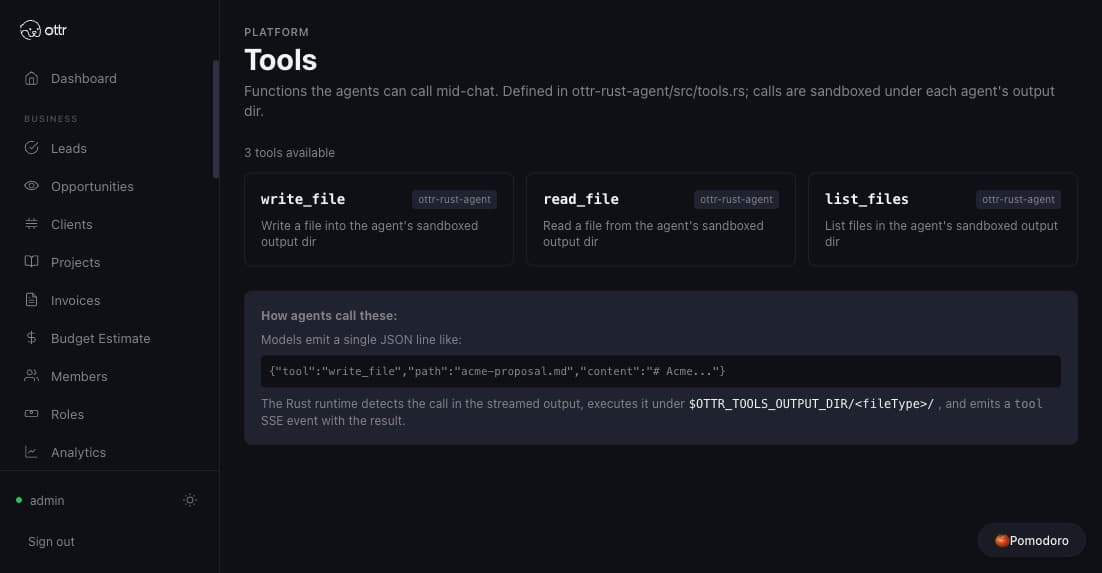
- Route models by prefix: Ollama on Metal locally, OpenRouter, OpenAI, Gemini or Groq in the cloud, with fallback chains, abort and a prompt CRUD API. Cheap local first, cloud when the task needs it.
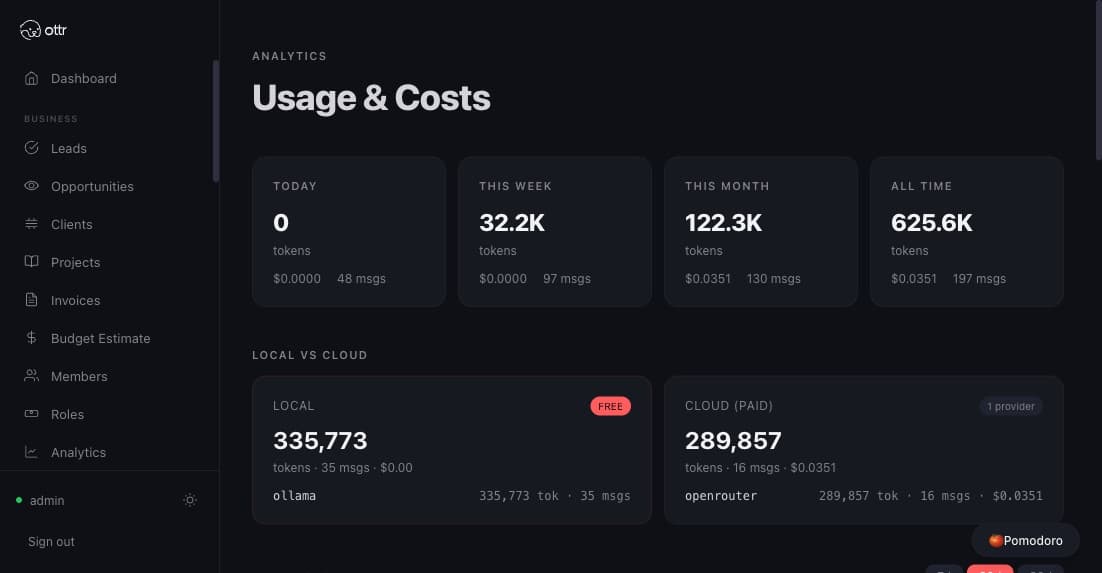
- Keep the product in NestJS. Dashboard modules for leads, proposals, invoices, wiki memory on pgvector, inference jobs on BullMQ, usage and cost, web push and backups.
- Opportunity scanner over Upwork, RemoteOK, Hacker News, We Work Remotely and Freelancer feeds, scored and pushed into a follow-up queue. Gmail, Google Calendar and GitHub PR webhooks as inputs.
- Boot-to-running recipe: macOS auto-login, launchd ordering for Postgres, Redis, Ollama, the runtime and the dashboard, autossh to the VPS, auto-restart after power loss.
Architecture
Outcome
- Runs unattended on a Mac Mini and comes back on its own after power loss.
- Local model reply latency dropped from tens of seconds to under one second by shrinking the prompt, before touching model choice.
- The runtime became the seed for AI-WORKER's model routing.
Lessons
- Prompt length is the first performance knob for local models, ahead of quantisation or hardware.
- An agency assistant is mostly a CRM with a model attached. The boring parts, leads and follow-ups, carried the value.